With 64 GiB of RAM and an RTX 5060 Ti 16GB, the latest measured medians for original Qwen3.8-Flash-Next IQ3_XXS are 1,665.73 tokens/s for Prefill and 51.65 tokens/s for Decode. This article compares model quality, memory usage and the speeds measured on my PC and the Strata author’s PC.
Strata series: Model benchmarks · Performance formula · Upgrade costs and benefits
Latest measurements: Strata 0.1.43.1
On October 13, 2026, I ran each test nine times on an i7-11700, RTX 5060 Ti 16GB and 64GB of dual-channel DDR4-3200, using the same prompts and settings as the 0.1.41 tests. Throughput is in tokens/s.
| Test | 0.1.41 | 0.1.43.1 | Speed change | New-version minimum–maximum |
|---|---|---|---|---|
| Prefill / nominal 32K | 1,666.44 | 1,665.73 | −0.04% | 1,642.28~1,672.80 |
| Decode / nominal 4K | 51.30 | 51.65 | +0.68% | 51.23~52.43 |
| Run | Prefill / nominal 32K | Decode / nominal 4K |
|---|---|---|
| 1 | 1,672.80 | 51.65 |
| 2 | 1,672.26 | 51.65 |
| 3 | 1,665.73 | 51.23 |
| 4 | 1,667.96 | 51.50 |
| 5 | 1,642.28 | 51.75 |
| 6 | 1,655.38 | 51.24 |
| 7 | 1,655.48 | 51.77 |
| 8 | 1,669.69 | 52.43 |
| 9 | 1,655.81 | 51.77 |
Settings: 65,536-token context, INT8 KV, KV resident 32,768, VRAM reserve 1,500 MiB, automatic expert cache and Prefill, MTP spec 4 / min-p 0.5, and greedy decoding. Every run started a fresh engine and generated 256 tokens. HTTP and vision services were stopped; the prompt cache was not reused. The OS file cache was not cleared. Model loading was excluded from the timing.
The nominal 32K / 4K prompts actually contained 31,566 / 3,562 tokens. Prefill timing covered 31,565 / 3,561 tokens, leaving the final prompt token for the first Decode step. The saved prompts were substitute source code, not the author’s unpublished original text. The two versions produced similar medians, but background activity and temperatures could not be reproduced perfectly. The cross-PC comparison and v4 formula below retain the 0.1.41 baseline.
Same-model comparison: local PC versus Strata author
| Item | Local PC | Strata author |
|---|---|---|
| CPU | Intel Core i7-11700 | AMD Ryzen 5 7600 |
| GPU | RTX 5060 Ti 16GB | RTX 5070 12GB |
| GPU link | PCIe 4.0 ×8 | PCIe 5.0 ×16 |
| RAM | 64GB DDR4-3200, dual channel | 64GB DDR5-5200, channel configuration unconfirmed |
Both IQ2_XS results use Swift 1.5; both IQ3_XXS results use original Qwen. Local figures are medians of nine runs per test on October 11, 2026; each author result is a single measurement. Times below are calculated for 51,200 input + 4,096 output tokens.
| Model / metric | Local speed | Author speed | Author speed increase | Local seconds | Author seconds | Author time saved |
|---|---|---|---|---|---|---|
| Swift IQ2_XS / Prefill | 1,622.10 | 2,092.02 | +29.0% | 31.6 | 24.5 | 22.5% |
| Swift IQ2_XS / Decode | 65.55 | 78.60 | +19.9% | 62.5 | 52.1 | 16.6% |
| Swift IQ2_XS / Total | — | — | — | 94.1 | 76.6 | 18.6% |
| Original IQ3_XXS / Prefill | 1,666.44 | 1,745.16 | +4.7% | 30.7 | 29.3 | 4.5% |
| Original IQ3_XXS / Decode | 51.30 | 61.64 | +20.2% | 79.8 | 66.5 | 16.8% |
| Original IQ3_XXS / Total | — | — | — | 110.6 | 95.8 | 13.4% |
Time saved = 1 − author time / local time. Speed increase = author tokens/s / local tokens/s − 1. Both use unrounded values. These are calculated model inference times, not measured end-to-end coding-agent task times.
The author used Strata 0.1.26 with an English MTP vocabulary; the local tests used 0.1.41 with a CJK MTP vocabulary. Prompts, context and KV conditions also differed, so the gap cannot be attributed entirely to hardware. Locally, original IQ3_XXS Prefill was 2.7% faster and Decode 21.7% slower than Swift IQ2_XS; this comparison changes both the model variant and quantization.
ISTA quantization quality: LiveCodeBench v6
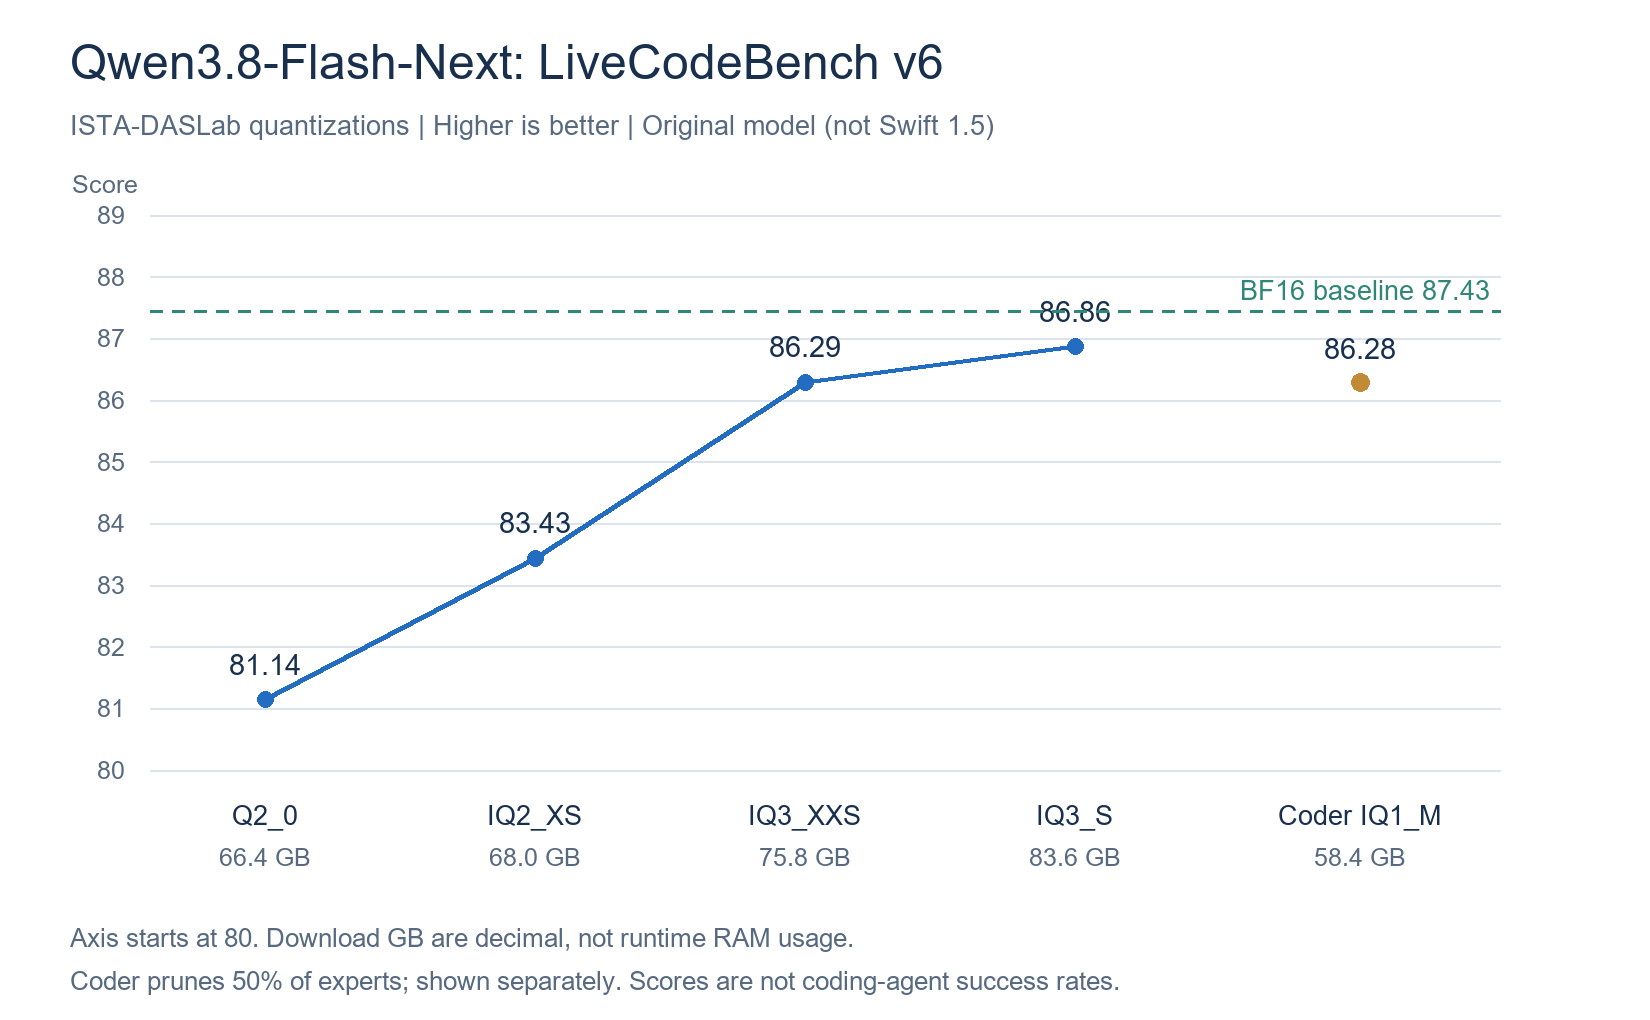
These are ISTA-DASLab evaluations of original-model quantizations; Swift 1.5 is excluded. Higher scores are better. Download sizes use decimal GB and are not runtime RAM usage.
| Variant | Download size (GB) | LiveCodeBench v6 |
|---|---|---|
| Q2_0 | 66.4 | 81.14 |
| IQ2_XS | 68.0 | 83.43 |
| IQ3_XXS | 75.8 | 86.29 |
| IQ3_S | 83.6 | 86.86 |
| Coder IQ1_M, 50% of experts pruned | 58.4 | 86.28 |
| Original BF16 baseline | — | 87.43 |
Moving from IQ3_XXS to IQ3_S adds 7.8 GB to the download and improves the score by 0.57 points. Coder is a separate expert-pruned variant, not simply a lower-precision quantization. The chart’s vertical axis begins at 80 to magnify differences. Coding-problem scores are not success rates for complete coding-agent tasks. Sources: ISTA original-model evaluations and the Coder model card.
How much of 64 GiB RAM remains?
Measured on October 13, 2026, with IQ3_XXS, a 65,536-token context and vision enabled. All capacities in this section use GiB.
| Item | GiB |
|---|---|
| Installed capacity | 64.00 |
| Total usable by Windows | 63.84 |
| Official RAM estimate | 45.63 |
| Capacity remaining after official estimate | 18.20 |
| Measured unload/reload increment, including vision | 44.12 |
| Capacity remaining after measured increment | 19.72 |
The remaining capacity still includes memory already used by Windows and other applications; it is not currently free RAM. The 44.12 GiB figure is the whole-system difference before and after unloading/reloading, influenced by caching and background activity; it is not exclusive process memory. The official and measured estimates are separate calculations and must not both be subtracted. Differences use unrounded values. Official reference: Strata model RAM estimates.
Benchmark sources
- The author’s Strata 0.1.26 benchmark notes and raw run data.
- Strata technical documentation.
- Local Swift tests used pinned model files. The author’s data did not include file SHA hashes, so byte-for-byte identity cannot be confirmed.
- The tester retains the nine-run raw outputs, prompts, settings and RAM measurement records. This article includes the summaries and individual new-version runs.


Discussion